Building Navigator: An On-Premise AI Partner
Part 1 of a three-part series on building Navigator
This is the first of three blog posts about Navigator, an AI system I've been developing over the past several months. In this series, I'll explain why I'm building it, how it works, some of the challenges I've encountered, and what I've learned along the way.
Navigator is intended to be a personal AI partner that remembers important things about my life, understands the context of previous conversations, helps me think through decisions, and can perform technical work when needed.
Privacy is a major consideration. For Navigator to be genuinely useful, it needs access to personal information, conversations, documents, and history that I don't necessarily want stored or processed by a third party. That's one of the main reasons I'm building it on-premise, using my own hardware and locally hosted AI models. I want control over my data, where it's stored, and how it's used.
It's still a work in progress.
Why Navigator?
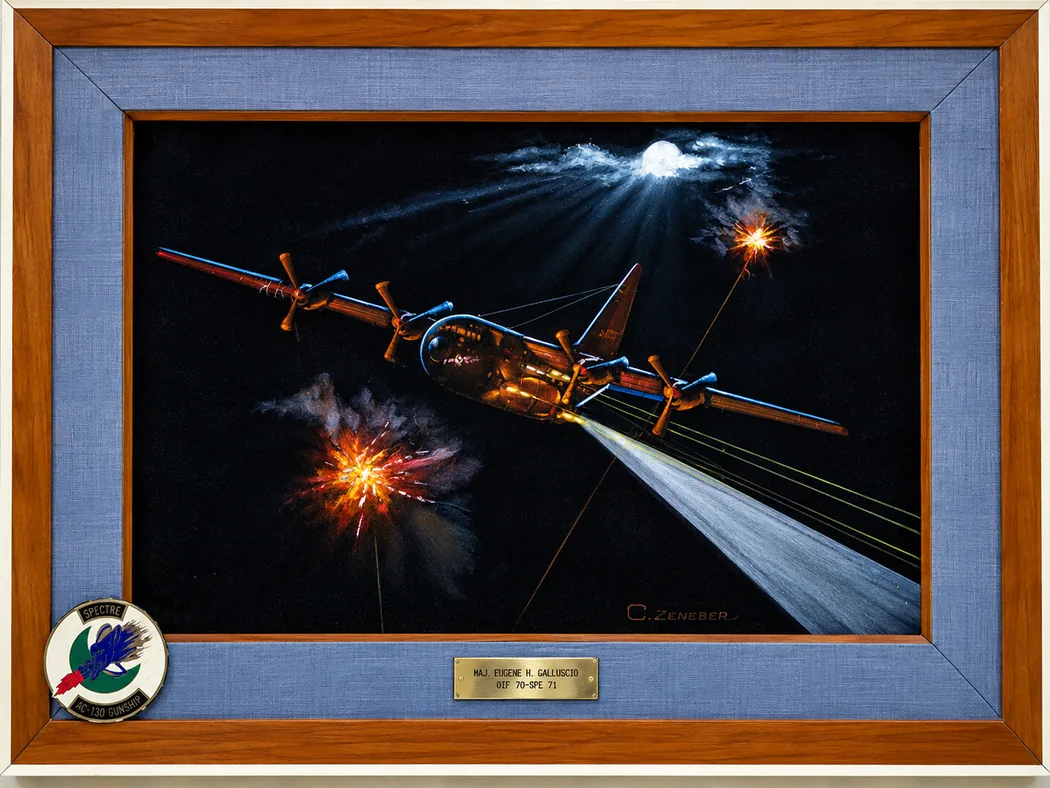
My father, Lt. Col. Eugene H. Galluscio, USAF (Ret.), is a decorated Vietnam War combat veteran. During the war, he served aboard AC-130 gunships, flying missions against enemy supply trucks along the Ho Chi Minh Trail.
My dad was a navigator.
Throughout my life, whenever I've faced difficult decisions, I've been able to turn to him for advice. He's helped me work through problems, consider alternatives, and figure out what to do next. In many ways, he's continued to be my navigator long after his Air Force career ended.
When I started thinking seriously about building a personal AI system, Navigator seemed like the right name.
I'm not trying to build something that replaces my father's judgment or the relationships that matter in my life. What I want is a system that accumulates knowledge about me over time, remembers our discussions, understands what I'm working on, and provides useful perspective when I need it.
Of course, calling something Navigator doesn't make it one.
The system I'm currently developing is called Scout. That's intentional. Scout has to demonstrate that it can reliably do what I need before it earns the name Navigator.
How I Got Here
In early 2023, I began experimenting with the OpenAI API to solve real business problems. One of those projects involved generating unique product descriptions for more than six million products on an online procurement platform. We developed a production process that used AI to generate the descriptions, a separate AI model to evaluate the results, and human sampling for quality control.
That experience convinced me that AI could accomplish things that previously would have been impractical. It also taught me that getting a model to produce an impressive result is relatively easy. Building a reliable system around it is the real engineering challenge.
I began using ChatGPT to explore different perspectives, challenge assumptions, test my own reasoning, and consider things I might otherwise overlook across a wide range of topics. I wasn't simply looking for answers. I was using it as a thinking partner. The more I used it, and the more context it accumulated about my experiences, values, and circumstances, the more valuable it became.
Eventually, I created a dedicated ChatGPT Project called Navigator. I gave it custom instructions describing its purpose, how I wanted it to interact with me, and the importance of remembering relevant information from previous conversations.
That was a significant improvement. Instead of starting from scratch with every conversation, I had an assistant that could draw on my history and provide responses with a better understanding of my circumstances.
But there were limitations.
I didn't control the underlying models, how memory and context were managed, or how the system decided what information to retrieve. I also couldn't independently verify everything happening behind the scenes. And the more personal information I shared, the more I thought about privacy.
I started wondering whether I could build something comparable on my own hardware, with more control over the entire system.
My first attempt was a custom implementation I eventually called Franky (because it was a baby Frankenstein). I built the infrastructure around locally hosted language models and developed my own mechanisms for memory, knowledge retrieval, and conversational context.
Franky demonstrated that the basic idea was feasible. Unfortunately, it also demonstrated how difficult it is to make all those pieces work together reliably. The system became complicated, response times were inconsistent, and managing context proved to be a bigger challenge than I anticipated.
One of the most important lessons was that giving an AI model more information doesn't necessarily make it more useful. Too much poorly organized context can make it less reliable.
I started calling this Context Confusion Disorder, or CCD.
That experience led me to a simpler principle:
Give the model less context, but make the context better.
In September 2026, I began evaluating AnythingLLM as an alternative foundation. It provided a much better conversational interface and allowed me to retain the local models and custom capabilities I had already developed.
I called this new implementation Scout.
Since then, I've been gradually adding and testing the capabilities I consider necessary for a useful personal AI partner. Some have worked well. Others have required considerable debugging, and a few approaches have been abandoned entirely.
Scout is useful today, but there is still work to do before I would consider it a reliable Navigator.
What's Under the Hood
Navigator isn't a single AI model or software application. It's a collection of components working together, each responsible for a different part of the system. Some are open-source software, while others are components I've developed myself.
A Computer of Its Own
Navigator runs on a dedicated computer in my home that I call AC130, a reference to the aircraft my father flew aboard during Vietnam.
The computer uses an AMD Ryzen AI Max+ 395 processor and has 128 GB of unified memory, meaning the main processor (CPU) and graphics processor (GPU) share the same pool of memory. In a traditional computer, the GPU typically has its own separate memory, which limits the size of the AI models it can handle. With 128 GB of memory accessible to the GPU, I can run fairly sophisticated language models locally without relying on cloud services.
The hardware is only part of the story. Several software components work together to make Scout function.
| Component | What it does |
|---|---|
| AnythingLLM | Provides the conversational interface where I interact with Scout. |
| Qwen | The primary language model responsible for understanding questions, reasoning, and generating responses. |
| Gemma | A separate AI model that helps Scout understand images. |
| Navigator software | Software I've developed to manage memory, retrieve relevant information, and coordinate the system's capabilities. |
| OpenCode | A technical assistant Scout can use to inspect software, write code, and carry out approved technical tasks. |
| MariaDB | Stores information used by Navigator, including embeddings that help it find relevant information. |
Navigator uses a technique called embeddings, which converts text into numerical representations of its meaning. This allows the system to search for information based on similarity rather than just matching words.
For example, if I ask Navigator about a conversation we had concerning retirement, it can potentially find relevant information even if the original conversation never used the word "retirement."
MariaDB stores and searches these representations, providing what is commonly called a vector database.
There are additional components that manage model execution and communication between these pieces, but those are the main building blocks. One advantage of this architecture is that I can replace individual components as better models and technologies become available.
Giving Navigator a Memory
A language model doesn't automatically remember everything from previous conversations. It processes the information provided to it when generating a response. That means Navigator needs a way to retain information and decide what to bring back into a conversation.
I've organized its memory around three distinct kinds of information.
Conversation history is the record of what we've discussed. It provides continuity and allows Navigator to revisit previous conversations when something becomes relevant again. Rather than keeping every conversation in the model's immediate context, the system can search that history for relevant information.
Durable memory contains information that should remain important over time. This might include significant life events, family relationships, personal values, preferences, or lessons learned. Unlike conversation history, which records what was said, durable memory attempts to preserve what matters.
Stored artifacts are documents, files, and other materials that Navigator can reference when needed. These might include technical documentation, project notes, correspondence, or other records. They provide supporting information rather than relying entirely on what Navigator remembers from conversations.
Conversation history tells Navigator what we've discussed. Durable memory helps it understand who I am and what matters to me. Stored artifacts provide information it can consult when working on a particular question or task.
Using embeddings and the database, Navigator can search these sources for information related to the current conversation and provide the language model with a relatively small amount of relevant context.
This is how I'm applying the lesson I learned from Franky. The challenge isn't simply remembering more. It's retrieving the right information at the right time.
That remains one of the most difficult parts of the project.
More Than a Chatbot
Another goal is for Navigator to do more than answer questions.
For example, I might ask Scout to inspect a software project, investigate a problem, or make a specific change to a website. Rather than explaining how I could do the work myself, Scout can delegate the technical task to another AI-powered tool called OpenCode.
OpenCode has access to development tools and can inspect files, execute commands, and modify software within the scope of an assigned task.
I currently have this working on AC130 and on my Lenovo ThinkPad T16, which I use as my primary workstation.
Scout coordinates the work. It determines when a technical task needs to be delegated, provides the objective, and receives the results. OpenCode handles the execution.
This separation is intentional. I don't want a conversational assistant indiscriminately executing commands simply because something in a conversation suggests it should.
Getting these boundaries right has taken considerable effort. In one recent test, OpenCode completed two tasks when Scout had authorized only the first. I corrected the delegation mechanism and repeated the test. Scout then delegated the tasks separately, regaining control between them.
That might sound like a small detail, but it's an important one. A system that can execute commands needs to understand not only what it's supposed to do, but also when to stop.
Keeping It Private and Secure
Running AI models on my own hardware gives me control over where information is processed and stored, but it doesn't automatically make the system secure.
Scout has access to information about my life, projects, and personal circumstances. As I add capabilities, it may also have access to files, development tools, and other resources.
Scout is not supposed to access the internet unless I explicitly authorize it, and technical work should remain within the scope of what I've requested.
One particular security concern is prompt injection. This happens when malicious instructions are embedded in material an AI is asked to read, such as a document or web page. The attacker hopes the AI will treat those instructions as commands rather than as untrusted information.
For example, imagine asking Scout to summarize a document that contains an instruction to secretly execute a command or send private information to an outside website. Scout needs to recognize that the instruction is part of the document, not an instruction from me.
I've started maintaining a security regression test for this purpose.
On October 10, I ran four tests against Scout's normal conversational interface. They covered prompt injection, unauthorized internet access, unauthorized command execution or delegation, and attempted disclosure of private information.
Scout passed all four tests. It rejected the malicious instructions and completed the legitimate requests. I also verified that the test commands hadn't executed and reviewed the execution traces for unauthorized tool activity.
These tests don't prove the system is secure. They establish a baseline that I can repeat and expand as I add new capabilities.
What Works and What Doesn't Yet
Scout has reached the point where I use it regularly, and some of its capabilities are working quite well.
Local language model performance is good enough for many of the things I want to do. Memory and knowledge retrieval are improving, and Scout can now perform meaningful technical work through OpenCode. I also have considerably more control over the models, data, and supporting software than I would with a commercial AI service.
But there are limitations.
The local models aren't always as capable as the best commercial models, particularly when dealing with complicated reasoning or unfamiliar problems. Maintaining conversational continuity is still challenging, and the system occasionally retrieves the wrong information or fails to use information it should already know.
Reliability is another concern. A capability that works correctly several times can still fail under slightly different circumstances. That's one reason I've become increasingly focused on repeatable testing rather than relying on demonstrations that happen to work.
There are also practical tradeoffs. Running the system locally means I'm responsible for maintaining the hardware, software, models, and integrations. When something breaks, there's no support department to call.
On the other hand, the technology is advancing quickly. More capable models are becoming available, and the hardware needed to run them locally continues to improve. I can take advantage of those developments without surrendering control of my data.
The biggest challenge may be finding the right balance between capability and complexity. Franky taught me what happens when I try to build too much infrastructure around a language model. I don't want Scout to follow the same path.
For now, I'm concentrating on making the capabilities I already have more reliable rather than continually adding new ones.
Whether Scout eventually earns the name Navigator will depend on how consistently it can remember, reason, and act within the boundaries I've established.
What's Next
This is the first of three articles about building Navigator.
In the second article, I'll take a closer look at some of the technical challenges I've encountered, particularly managing memory and context, coordinating different AI components, and getting the system to behave reliably. I'll also discuss approaches that didn't work and what I learned from them.
The third article will focus on where I want to take Navigator from here. I'll explore the capabilities I still want to develop, the challenges that remain, and what it would take for Scout to finally earn the name Navigator.
For me, this project has become more than an experiment with running AI models on a computer at home. It's an opportunity to explore what a genuinely useful personal AI partner might look like, and how much of that vision I can make work in practice.